VGAP — Bridging Visual Generation and Perception
We work at the intersection of Computer Vision and Generative AI — image synthesis, multi-modal LLMs, vision backbones, 3D vision, and uncertainty-aware perception. Our mission is world-class research, published at top-tier venues and applied to real-world problems for industry and government.
Bridging the gap between generation and perception.
Explore our work published at top-tier venues in Computer Vision and Machine Learning.
Browse publications →SolutionsSee how our research can solve your real-life problems
From automated code compliance in construction, to automated AI assistants, and smart-city traffic monitoring — see how our research translates into deployed, working systems.
See our solutions →Featured publications
View all →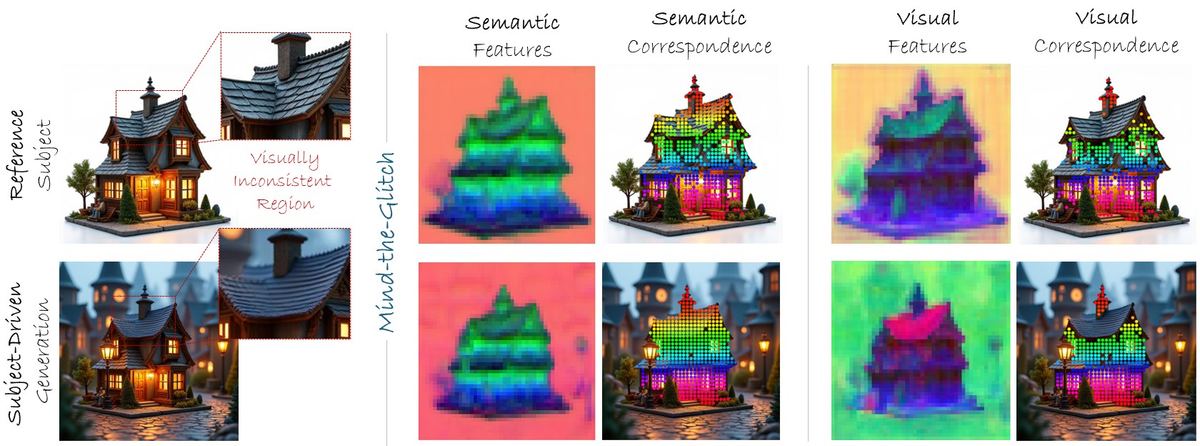
Mind-the-Glitch: Visual Correspondence for Detecting Inconsistencies in Subject-Driven Generation
Introduces a method for detecting visual inconsistencies in subject-driven image generation by leveraging visual correspondence, improving reliabil…
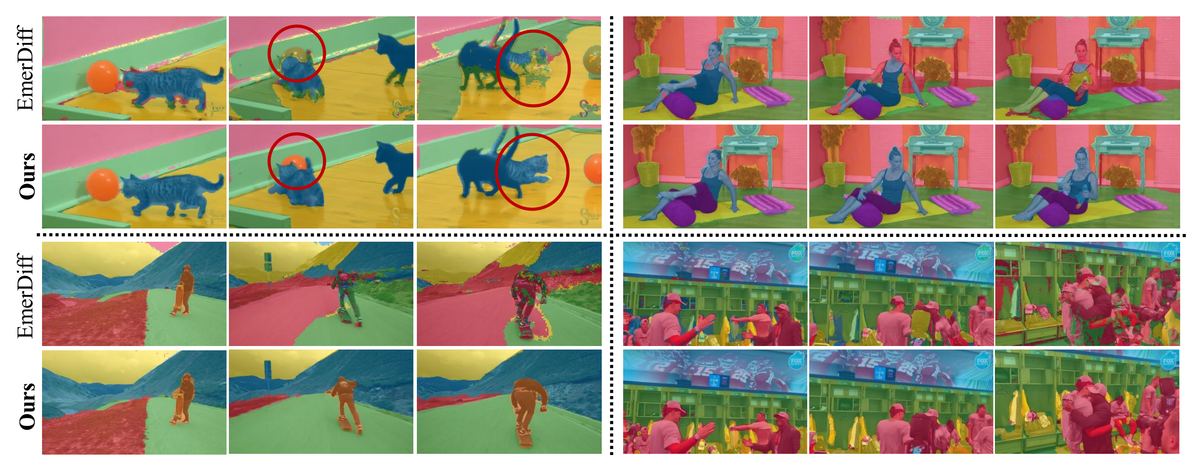
VidSeg: Zero-Shot Video Semantic Segmentation based on Pre-Trained Diffusion Models
Repurposes pre-trained diffusion models for zero-shot semantic segmentation of video, removing the need for task-specific labeled training data.
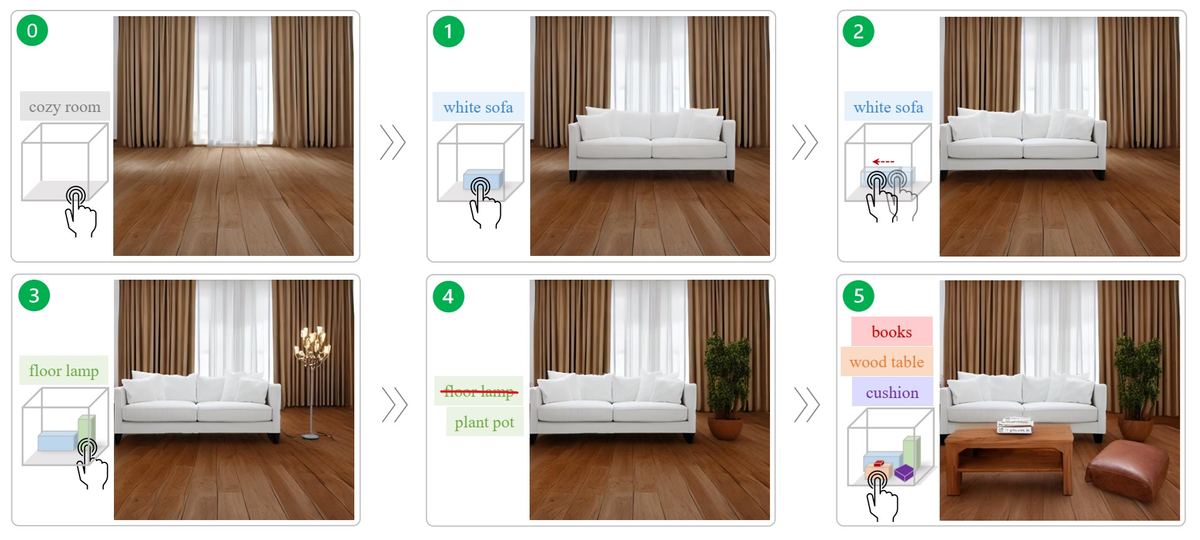
Build-A-Scene: Interactive 3D Layout Control for Diffusion-Based Image Generation
Gives users interactive, explicit control over 3D object layout when generating images with diffusion models, closing the gap between free-form pro…


Latest news
View all →VGAP Lab launches at HBKU
We're launching VGAP — the Computer Vision, Generative AI & Perception Lab at HBKU — bringing together academic research and applied AI work for government and industry partners across Qatar and the GCC.
"Mind-the-Glitch" accepted as a Spotlight at NeurIPS 2025
Our paper on detecting visual inconsistencies in subject-driven generation was accepted as a Spotlight presentation at NeurIPS 2025.
Four papers accepted at ICCV, SIGGRAPH & ICLR 2025
EditCLIP, PlaceIt3D and ZeroKey were accepted at ICCV 2025, PartEdit at SIGGRAPH 2025, and Build-A-Scene at ICLR 2025 — a strong showing across generative AI and 3D vision venues.